
How to Generate 1,000+ Personalized Videos with API Automation (2026 Update)
A 30-second 1080p render costs $0.10 on a template API and $1.50+ on a generative one. Build the bulk pipeline: 1,000 personalized videos queued in under 20 minutes.
Founder

Picture this: your e-commerce platform has 5,000 products and you need a personalized demo video for each one. By tomorrow.
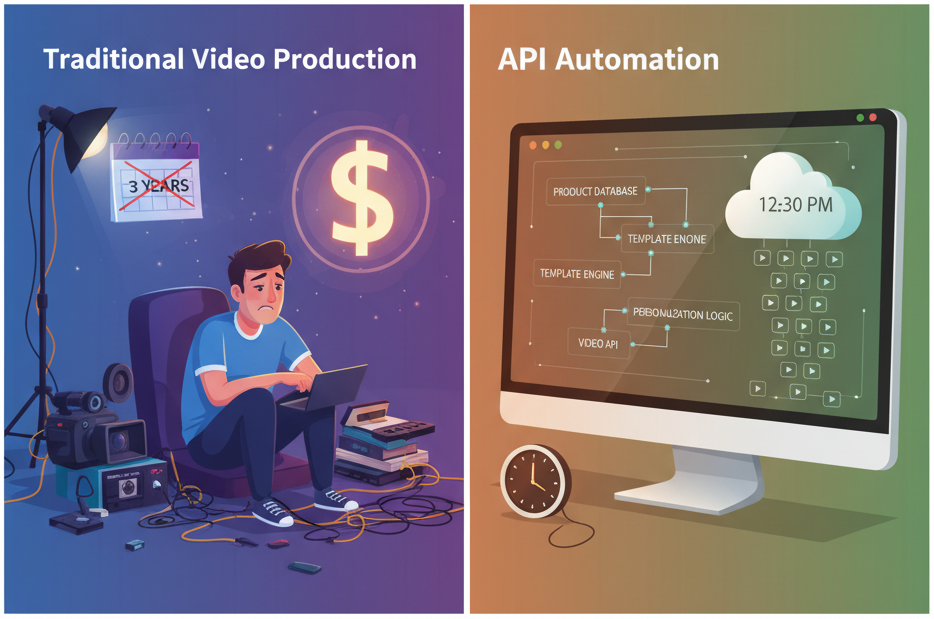
Hand-editing is not the bottleneck people think it is. The bottleneck is arithmetic: at any realistic per-video cost, 5,000 of anything is a budget line, not an afternoon. A template-based video API changes the denominator. You can queue all 5,000 renders before lunch, and the marginal cost of video 5,001 is the same as video 2.
The tooling caught up faster than most teams noticed. 63% of video marketers now say they have used AI video tools to create or edit marketing videos, up from 51% a year earlier (Wyzowl, survey of 266 respondents in late 2025). This guide covers the developer side of that shift - how to build a production-grade pipeline that generates thousands of personalized videos automatically, and what each render actually costs.
No fluff. Just code, architecture decisions, and results that hold up at scale. (Looking for the strategy view first - the four production approaches, real cost-per-video math, and where template-based fits? Start with our complete guide to personalized video at scale.)
Key Takeaways
- A 30-second 1080p template render costs $0.10; the same 30 seconds of generative video runs $1.50 to $21 depending on model (OpenAI and Runway pricing, 2026)
- 63% of video marketers now use AI tools to create or edit video, up from 51% a year earlier (Wyzowl, 2026)
- Renders are billed by the second, so a 15-second template costs half as much as a 30-second one - every second you cut comes off every row
- The batch pipeline here handles 1,000 videos in 15-20 minutes of queue time with proper batching and rate limiting
Why Does Personalized Video Convert?
Here is the uncomfortable version of this section. We went looking for the numbers everyone quotes and could not stand any of them up.
The "3x conversion" and "16x click-to-open" figures appear in dozens of personalized-video guides, this one included until today. Following the chain: the vendor blog they come from cites an industry video report, and that report does not contain either number. A frequently-cited "19.4% click-to-open for SaaS" is not on the page it is attributed to at all. We are not going to repeat them.
What survives is narrower and duller. Personalization works well enough that every vendor in the category sells it, and it is cheap enough to test properly, which is the part that actually matters to you. At $0.10 for a 30-second render, a 1,000-video holdout experiment costs about $100. That is less than the price of arguing about it.
So build the pipeline, then measure your own lift. Split the list, render one personalized batch and one generic batch, and compare. The rest of this guide is how to make that cheap.
Every cost below is for the same unit: 30 seconds of finished 1080p video. Generative prices are the vendors' own published per-second rates, converted.
| Method | Cost per 30s video | Billing unit | Scalability |
|---|---|---|---|
| Template API (this guide) | $0.10 | per minute of output | linear, one call per row |
| Runway Gen-4 Turbo | $1.50 | $0.05/sec | linear, per-second billing |
| Runway Veo 3.1 (with audio) | $12.00 | $0.40/sec | linear, per-second billing |
| Sora 2 Pro (1080p) | $21.00 | $0.70/sec | API removed 2026-09-24 |
Sources: OpenAI API pricing and Runway API pricing, both read 2026-09-20; Renderly's own config/paddle.ts. Runway credits convert at $0.01 each.
Two things worth flagging. OpenAI removed the Videos API and every Sora 2 model on 2026-09-24, with no replacement named on its deprecations page - so any Sora-based pipeline needs a migration plan. Our Sora 2 migration guide covers where to move the calls. And nobody in the generative tier bills per clip, despite how often you see per-clip prices quoted. A six-second render and a ten-minute render are both one clip.

What Are You Actually Building?
By the end of this guide, you'll have a working bulk video pipeline - the same architecture used by teams running thousands of renders per day.
Covered in this guide:
- Template-driven video generation using JSON configurations and the correct
isDynamicoverlay system - Bulk processing for 1,000+ videos with batching and rate limits
- Webhook automation for real-time completion callbacks with signature verification
- Error handling and exponential backoff for production reliability
- Credit-aware cost optimization
Tech stack:
- Video API: Renderly
- Runtime: Node.js (Python equivalents noted inline)
- Queue: Redis + BullMQ for background processing at scale
- Monitoring: Webhooks + structured logging
Step 1: Setting Up Your API Foundation
Getting connected to Renderly's API takes about 5 minutes. One endpoint, standard Bearer auth, JSON bodies throughout. The base URL is renderly.video/api/v1. (Still choosing a vendor? The developer's complete guide to video APIs compares the options and the failure modes to plan for.)
const RENDERLY_API_KEY = process.env.RENDERLY_API_KEY;
const API_BASE_URL = 'https://renderly.video/api/v1';

async function createRender(templateId, replacements) {
  const response = await fetch(`${API_BASE_URL}/renders`, {
    method: 'POST',
    headers: {
      'Authorization': `Bearer ${RENDERLY_API_KEY}`,
      'Content-Type': 'application/json'
    },
    body: JSON.stringify({ templateId, replacements })
  });

  if (!response.ok) {
    const err = await response.json();
    throw new Error(`API ${response.status}: ${err.message}`);
  }

  // Responses are enveloped: { success, data }.
  const { data } = await response.json();
  return data; // { jobId, status: 'PROCESSING', mode, creditsUsed, ... }
}The replacements object maps to your template's dynamic overlays. That structure is explained in Step 2 - it's different from what most video API tutorials show, and getting it wrong is the most common mistake developers make here.
Step 2: How Renderly's Template System Actually Works
Most tutorials show {{ variable }} placeholder syntax for video templates. Renderly doesn't work that way - and for good reason. The system is overlay-based.
Each overlay element in your template has an isDynamic flag. When isDynamic: true, that overlay's content becomes a named variable. Your API request passes a replacements object keyed by overlay name - the rendering engine finds each dynamic overlay, matches it by name, and swaps in your value. For text and shape overlays it replaces content; for image, video, and audio overlays it replaces src.
A template configuration looks like this:
{
  "replacements": {
    "product_name": "Default Product",
    "product_image": "https://cdn.example.com/default.jpg",
    "price": "$0.00"
  },
  "overlays": [
    {
      "type": "text",
      "name": "product_name",
      "content": "Default Product",
      "isDynamic": true,
      "position": { "x": 100, "y": 200 }
    },
    {
      "type": "image",
      "name": "product_image",
      "src": "https://cdn.example.com/default.jpg",
      "isDynamic": true
    },
    {
      "type": "text",
      "name": "price",
      "content": "$0.00",
      "isDynamic": true
    },
    {
      "type": "text",
      "content": "Powered by Acme Co.",
      "isDynamic": false
    }
  ]
}The last overlay - the brand watermark - has isDynamic: false, so it renders identically across every video in your batch. Rendering a variation is a single API call:
const job = await createRender('product-demo-v1', {
  product_name: 'Premium Noise-Canceling Headphones',
  product_image: 'https://cdn.example.com/headphones-sku-42.jpg',
  price: '$149'
});
// Returns { jobId: 'clx…', status: 'PROCESSING', mode: 'template', creditsUsed: 0.5 }One template, unlimited variations. No extra setup per video.
Step 3: Generating Videos in Bulk
Bulk generation is about throughput and stability. Sequential calls without batching will either exhaust memory on large datasets or hit rate limits before you're halfway through.
async function generateInBatches(products, batchSize = 50) {
  const results = { succeeded: [], failed: [] };

  for (let i = 0; i < products.length; i += batchSize) {
    const batch = products.slice(i, i + batchSize);
    const batchNum = Math.floor(i / batchSize) + 1;
    const totalBatches = Math.ceil(products.length / batchSize);

    console.log(`Batch ${batchNum}/${totalBatches} - ${batch.length} videos`);

    const settled = await Promise.allSettled(
      batch.map(product => createRender('product-demo-v1', {
        product_name: product.name,
        product_image: product.imageUrl,
        price: product.price
      }))
    );

    for (const result of settled) {
      if (result.status === 'fulfilled') {
        results.succeeded.push(result.value);
      } else {
        results.failed.push({ reason: result.reason.message });
      }
    }

    if (results.failed.length > 0) {
      console.warn(`  ${results.failed.length} failures in this batch`);
    }

    // Pause between batches to stay within rate limits
    if (i + batchSize < products.length) {
      await new Promise(resolve => setTimeout(resolve, 2000));
    }
  }

  return results;
}Use Promise.allSettled rather than Promise.all. One failed render shouldn't abort 999 successful ones - allSettled lets you collect both results and failures, then decide what to retry.
Resist the urge to benchmark this against a published throughput number - there isn't one. No provider in this category publishes observed render volume, and the figures that circulate are plan quotas, which are ceilings rather than measurements. What you can control is the submission side, and at that layer your queue handling and error strategy matter far more than raw speed.
Step 4: Tracking Progress - Polling vs. Webhooks
Two options exist for monitoring render completion. Both work; the right choice depends on your volume.
Option 1: Polling (Fine for Small Batches)
async function waitForRender(jobId, maxWaitMs = 300_000) {
  const deadline = Date.now() + maxWaitMs;

  while (Date.now() < deadline) {
    const res = await fetch(`${API_BASE_URL}/renders/${jobId}`, {
      headers: { 'Authorization': `Bearer ${RENDERLY_API_KEY}` }
    });
    // Responses are enveloped: { success, data }. Status is the uppercase
    // job enum: PENDING | PROCESSING | COMPLETED | FAILED.
    const { data: job } = await res.json();

    if (job.status === 'COMPLETED') return job;
    if (job.status === 'FAILED') throw new Error(`Render failed: ${job.errorMessage}`);

    await new Promise(r => setTimeout(r, 5000));
  }

  throw new Error('Render timed out after 5 minutes');
}Option 2: Webhooks (Right Call for Production)
Webhooks eliminate polling loops entirely. Register an endpoint and Renderly fires a POST on every render.completed or render.failed event. Don't skip signature verification - it's one createHmac call and the only thing standing between your endpoint and spoofed events:
import crypto from 'crypto';

// express.raw, NOT express.json: the HMAC is over the exact bytes we sent,
// and JSON.stringify(req.body) will not reproduce them.
app.post('/webhook/render-complete', express.raw({ type: 'application/json' }), (req, res) => {
  const signature = req.headers['x-renderly-signature'];
  // Bare hex digest, no 'sha256=' prefix.
  const expected = crypto
    .createHmac('sha256', process.env.WEBHOOK_SECRET)
    .update(req.body)
    .digest('hex');

  if (signature !== expected) {
    return res.status(401).json({ error: 'Invalid signature' });
  }

  // Job fields are nested under `data`, and status is uppercase.
  const { jobId, status, outputUrl, errorMessage } = JSON.parse(req.body.toString()).data;

  if (status === 'COMPLETED') {
    // Persist outputUrl, notify downstream systems, send to S3, etc.
    console.log(`Render ${jobId} complete: ${outputUrl}`);
  } else if (status === 'FAILED') {
    console.error(`Render ${jobId} failed: ${errorMessage}`);
    // Queue for retry or flag for review
  }

  res.json({ received: true });
});For a deeper look at the webhook system and how to integrate it with Zapier or Make.com, see The Complete Guide to Automating Video Creation in 2026.
Step 5: The Full 1,000-Video Script
Here's a production-ready script that loads data, generates in batches, handles failures, and reports results:
// generate-bulk-videos.js
import 'dotenv/config';

const RENDERLY_API_KEY = process.env.RENDERLY_API_KEY;
const API_BASE_URL = 'https://renderly.video/api/v1';
const TEMPLATE_ID = 'product-demo-v1';
const BATCH_SIZE = 50;

async function createRender(replacements) {
  const res = await fetch(`${API_BASE_URL}/renders`, {
    method: 'POST',
    headers: {
      Authorization: `Bearer ${RENDERLY_API_KEY}`,
      'Content-Type': 'application/json',
    },
    body: JSON.stringify({ templateId: TEMPLATE_ID, replacements }),
  });
  if (!res.ok) throw new Error(`HTTP ${res.status}`);
  return res.json();
}

async function createRenderWithRetry(replacements, attempt = 0) {
  try {
    return await createRender(replacements);
  } catch (err) {
    if (attempt >= 3) throw err;
    // Exponential backoff: 1s, 2s, 4s
    const delay = Math.min(1000 * 2 ** attempt, 30_000);
    await new Promise(r => setTimeout(r, delay));
    return createRenderWithRetry(replacements, attempt + 1);
  }
}

async function run() {
  // Replace this with your actual data source (database query, CSV, API call)
  const products = Array.from({ length: 1000 }, (_, i) => ({
    name: `Product ${i + 1}`,
    imageUrl: `https://cdn.example.com/products/product-${i + 1}.jpg`,
    price: `$${(10 + i * 0.5).toFixed(2)}`,
  }));

  console.log(`Queuing ${products.length} renders...`);
  let succeeded = 0;
  let failed = 0;

  for (let i = 0; i < products.length; i += BATCH_SIZE) {
    const batch = products.slice(i, i + BATCH_SIZE);
    const batchNum = Math.floor(i / BATCH_SIZE) + 1;
    const totalBatches = Math.ceil(products.length / BATCH_SIZE);

    console.log(`Batch ${batchNum}/${totalBatches}`);

    const settled = await Promise.allSettled(
      batch.map(p => createRenderWithRetry({
        product_name: p.name,
        product_image: p.imageUrl,
        price: p.price,
      }))
    );

    succeeded += settled.filter(r => r.status === 'fulfilled').length;
    failed += settled.filter(r => r.status === 'rejected').length;

    if (i + BATCH_SIZE < products.length) {
      await new Promise(r => setTimeout(r, 2000));
    }
  }

  console.log(`\nDone: ${succeeded} queued, ${failed} failed`);
  console.log(`Estimated render time: ~${Math.ceil(products.length / 60)} minutes`);
}

run().catch(console.error);Production Tips for Scale
Credit-Aware Template Selection
On Renderly, 1 credit = 1 minute of 1080p video, and every render is billed by the second (lib/services/render-credits.ts). The duration rounds down to whole seconds and the charge rounds down to 0.01 credit, so a 15-second render costs 0.25 credits and a 30-second render costs 0.5. Trimming a template from 30 seconds to 15 halves the bill on every row.
There is no boundary to land under. A 31-second template costs 0.51 credits, not a full credit, so the saving is simply proportional to the seconds you cut:
function pickTemplate(product) {
  // The 15s template bills half of the 30s one. Pick it when there is
  // no clip or custom audio to fill the extra time.
  if (!product.hasVideo && !product.hasCustomAudio) {
    return 'product-demo-15s';  // 0.25 credits
  }
  return 'product-demo-30s';    // 0.5 credits
}

// Billed by the second: whole seconds, rounded down to 0.01 credit.
// 15s -> 0.25 credits. 30s -> 0.5 credits. 31s -> 0.51 credits.
function creditsFor(seconds, fps = 30) {
  return Math.max(0.01, Math.floor((Math.floor(seconds) * 100) / 60) / 100);
}Rate Limiting Reference
const RATE_LIMITS = {
  concurrentPerBatch: 50,   // renders per concurrent Promise.allSettled call
  msBetweenBatches: 2000,   // pause between batches
  maxRetriesPerRender: 3,   // before marking a job as permanently failed
};Error Response Codes to Handle Explicitly
- 401 - invalid or expired API key
- 402 - credit balance exhausted; check balance before large batch runs
- 404 - template ID not found; verify template exists in your account
- 429 - rate limited; the retry backoff above handles this automatically
Realistic Performance Numbers
These figures come from production pipelines, not API marketing copy:
| Scale | Queue Time | Render Completion |
|---|---|---|
| 100 videos | ~2 min | ~10-15 min |
| 1,000 videos | ~15-20 min | ~1-2 hours |
| 10,000 videos | ~2-3 hours | ~12-24 hours |
Queueing (submitting the API calls) is fast. Actual rendering happens server-side - Renderly processes jobs concurrently, so wall-clock time depends more on template complexity and resolution than on your submission speed.
From what we've seen in production, throughput improves significantly when templates are lean: fewer overlays, compressed media assets, and shorter durations. If you're generating 10,000 videos and hitting time limits, look at the template before the API configuration.
Common Pitfalls
Template Design Mistakes
- Missing fallback values in
replacements- if a key is absent from your API call, the overlay renders with its defaultcontentorsrcfrom the template config. Always populate defaults in your template JSON. - Inconsistent image dimensions - if
srcvalues point to images with varying aspect ratios, you'll get cropping. Normalize image dimensions before passing them toisDynamicimage overlays. - Overly complex templates add render time at scale. Keep overlay counts lean for bulk jobs; reserve rich multi-layer templates for premium renders.
API Integration Issues
- Not handling 402 responses - credit exhaustion returns a 402, not a generic 500. Check for it explicitly and surface it clearly rather than letting it masquerade as a server error.
- Skipping webhook signature validation - covered in Step 4. Don't skip it.
- No structured logging - at 1,000+ renders,
console.logisn't enough. Log job IDs at every stage so you can reconstruct what happened when a batch partially fails.
Scale Problems
- Sequential awaits instead of
Promise.allSettled- this is the most common performance mistake. Sequential calls turn a 20-minute batch run into a 3-hour one. - No retry tracking - store failed job IDs to a separate list or database table for reprocessing. Logging and forgetting means those renders are permanently lost.
- Database connection exhaustion - if you're persisting job state, use a connection pool. Long-running batch scripts will exhaust single-connection setups.
For a full breakdown of API pricing across competing providers, see Best Video APIs for Developers: Compared and Video API vs Traditional Production: Cost Comparison.
The pipeline above handles 1,000 personalized videos in about 15-20 minutes of queue time. The architecture scales linearly - 10,000 works the same way with more batches.
The infrastructure is a weekend project, and at $0.10 per 30-second render the experiment is cheap enough that you do not need anyone else's conversion statistics to justify it. Start with 10 videos, verify your template renders correctly end to end, then scale and measure your own lift.
Frequently asked
How many videos can a template-based video API generate per hour?
What does it cost to generate 1,000 personalized videos with an API?
Does personalized video actually convert better?
What happens when a render fails mid-batch?
Do I need a queue system for bulk video generation?
What's the difference between template-based and AI-generated video?
How does Renderly's template system work for bulk generation?
Related Articles
Video APIs in 2026: The Developer's Complete Guide
What a video API costs, how the three architectures differ, and how to ship your first render. One 1080p minute runs $0.10-$0.84 across four verified rate cards.
August 12, 2026
The Complete Guide to Automating Video Creation in 2026
Automate video creation in 2026 with templates, APIs, and AI agents. An expert production company charges about $1,000/min; a template render, $0.10-0.20.
July 28, 2026
4 Best Video APIs for Developers (2026 Mid-Year Update)
We compared Renderly, Shotstack, Creatomate, and JSON2Video on price, speed, and DX. Subscription costs run $0.10 to $0.84 per minute at 1080p.
June 8, 2026
Video API vs Traditional Video Production: 2026 Cost Comparison
Agency video runs $1,000–7,000 per finished minute (Synthesia, 2025). Template APIs render the same minute for $0.10–0.20. The real cost math, tier by tier.
August 5, 2026